
tag: databases
articles: 26 · beats: 5
latest: November 17, 2026
---
Databases
26 Crashtech articles on Databases, spanning System Design & Architecture, Databases, Architecture, Database Engineering and Development Best Practices, published between March 2026 and November 2026. Every piece is full-text HTML with sources, structured data and an authored FAQ.
They span System Design & Architecture (17), Databases (4), Architecture (2), Database Engineering (2), Development Best Practices (1). System Design & Architecture Databases Architecture Database Engineering Development Best Practices
Database Performance is a Trade-Off Ledger: The Hidden Costs of Indexing, Caching, and Sharding
Why every database optimization creates a new liability: the hidden write costs of B-tree indexes, caching stale reads, and sharding operational taxes.
Eventual Consistency in Distributed Databases: Replication Lag, Conflict Resolution, and Tuning
Why modern distributed databases trade immediate sync for availability: replication lag, conflict resolution algorithms, PACELC theorem, and monotonic reads.
Event Sourcing in Practice: Immutable Logs, Temporal State Replay, and CQRS Projections
Why systems should remember how they got here, not just where they are: exploring Event Sourcing, append-only logs, snapshots, and CQRS projections.
The Scaling Ladder: How Nextdoor Evolved PostgreSQL Through Pooling, Replication, and Sharding
How Nextdoor scaled PostgreSQL from a single server to a multi-tiered architecture: PgBouncer connection pooling, read replicas, and horizontal sharding.
Relational Database Design Guide: Keys, Relationships, Normalization, and Joins
A comprehensive guide to relational schema design, primary and surrogate keys, normal forms (1NF to BCNF), and indexing join performance trade-offs.
Strong Consistency in Distributed Databases: Linearizability, Raft Consensus, and Coordination Latency
What strong consistency actually costs in distributed systems: linearizability, Raft quorum consensus, physical latency floors, and failover boundaries.
Database Sharding: What It Actually Costs When You Split the Database
Sharding scales a database past one machine's limits, but it changes joins, transactions, and query patterns. Here's what each strategy trades away.
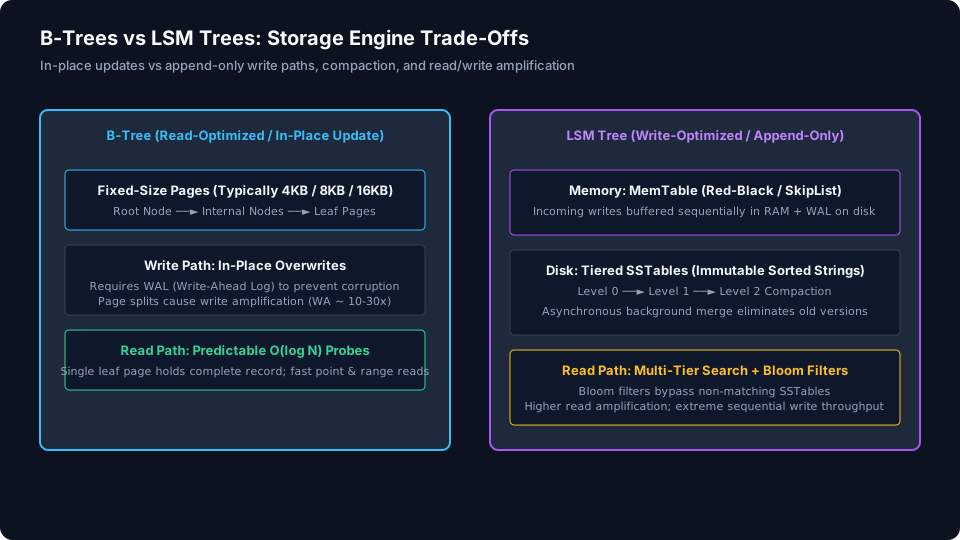
B-Trees vs LSM Trees: Storage Engine Trade-Offs and Compaction Mechanics
Compare B-Tree in-place updates against LSM Tree append-only storage engines: write amplification, Bloom filters, and compaction strategies.

Database Sharding Guide: Horizontal Partitioning, Shard Keys, and Cross-Shard Joins
Why databases resist horizontal scaling: deep dive into database sharding, range vs hash vs directory strategies, cross-shard joins, and resharding.
Database Types Guide: Storage Models, Access Patterns, and Polyglot Persistence
A practical guide to modern database types: relational, columnar, key-value, document, time-series, graph, and vector engines matching storage to workloads.
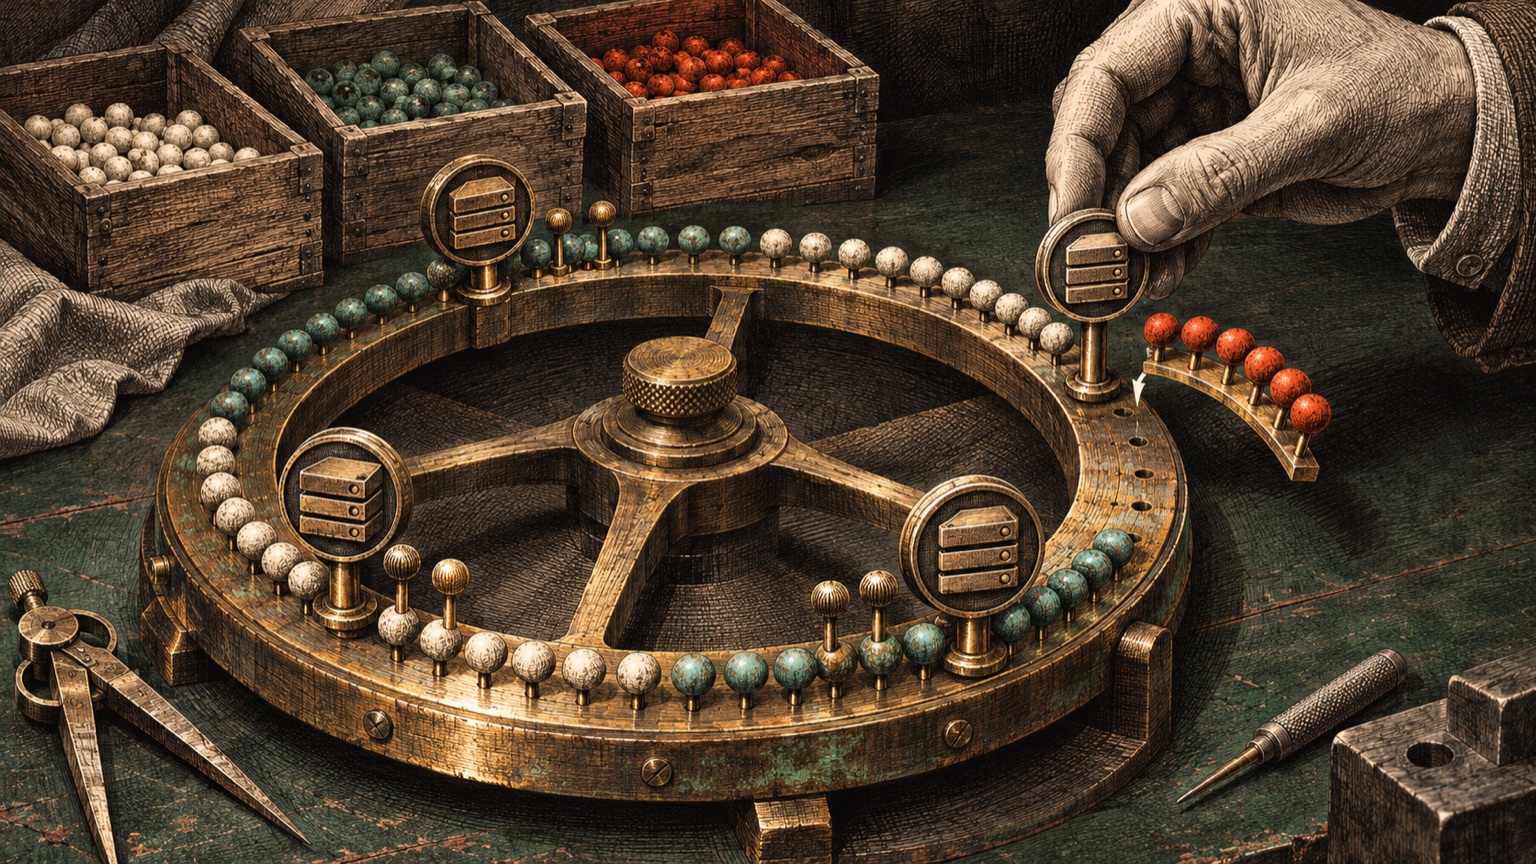
Consistent Hashing: What Moves When a Node Joins or Fails?
Understand hash rings, virtual nodes, data movement and operational caveats through Dynamo, Cassandra and Redis Cluster's contrasting slot design.
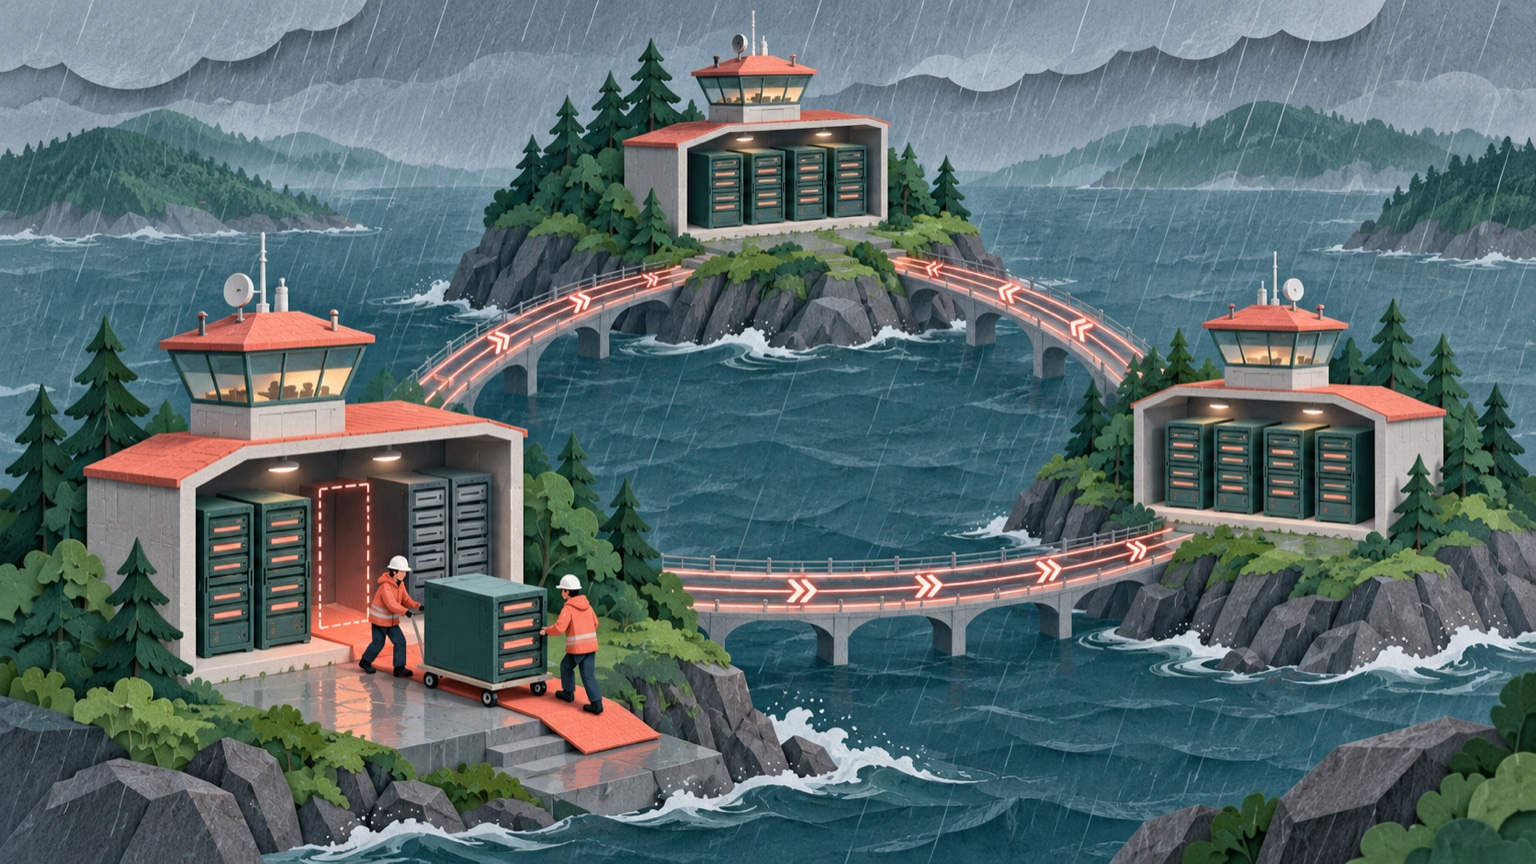
Airbnb’s Database-on-Kubernetes Design: Availability Through Safer Replacement
Airbnb’s engineering team explains why it runs one database across three Kubernetes clusters and serializes node replacement to protect quorum.
Inside Flipkart Altair’s MySQL Failover: Detection, Fencing, and Discovery
Flipkart’s Altair account shows why MySQL failover depends on false-positive checks, replica lag, fencing, and client rediscovery.
GitHub’s October Outages Show Why Regional Failover Needs Isolation
GitHub’s October reliability report describes runner queues and a saturated database pool. Teams can turn those incidents into practical dependency tests.
What Actually Happens Between You Hitting Enter and Rows Coming Back
A SQL query passes through five stages before you see a row: connection, parsing, planning, execution, storage. What each does and where it breaks.
PostgreSQL 19 Is Still an RC. Start the Upgrade Rehearsal
PostgreSQL 19 RC1 is not a production release. Review its maintenance and replication changes, then rehearse compatibility and rollback before the planned GA.
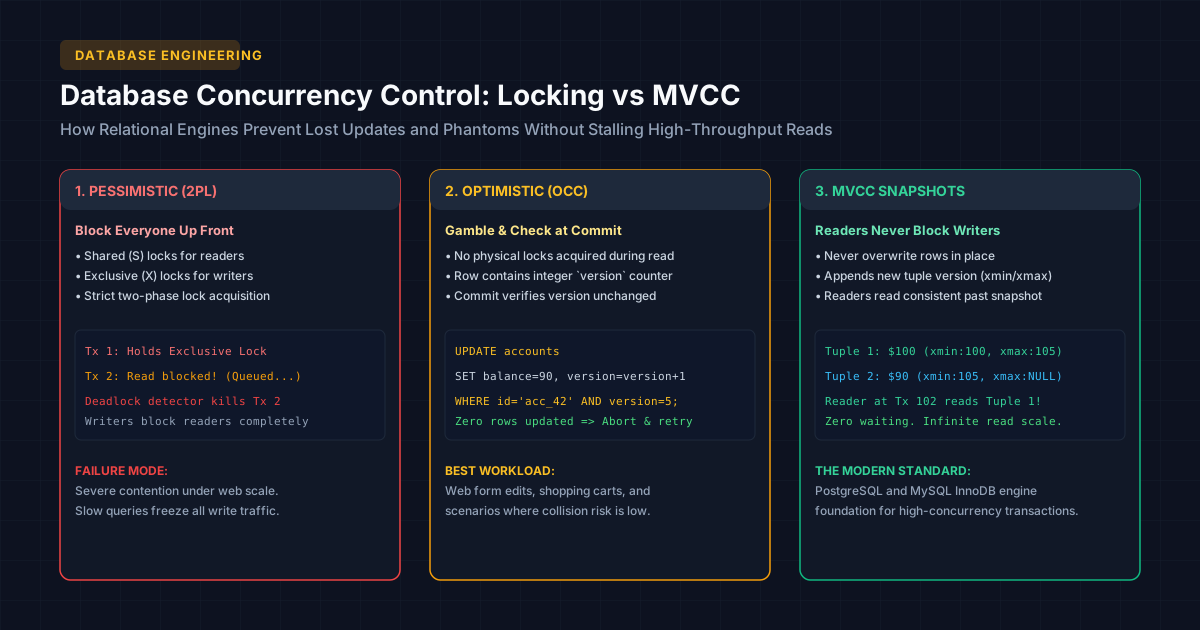
Concurrency Control in Databases: Lost Updates, Locking, and Isolation Levels Explained
How concurrent transactions corrupt state: dirty reads, non-repeatable reads, phantom reads, pessimistic locks, and MVCC snapshot isolation.
What Actually Happens Inside a Database Index: The Data Structures
An index trades disk I/O for lookup speed. Here's how B-trees, hash tables, and bitmap indexes each make that trade differently.
Database Indexing Explained: Which Index Type Actually Fits Your Query
B-tree, hash, composite, and covering indexes each solve a different query shape. Pick the wrong one and you pay index overhead without the speedup.
Database Replication Explained: Single-Leader, Multi-Leader, and Leaderless
What replication lag actually breaks, and how single-leader, multi-leader, and leaderless models trade off consistency for availability.
Database Transactions Explained: ACID, Isolation Levels, and Concurrency Control
What ACID actually guarantees, and how pessimistic vs optimistic concurrency control decide whether your app locks or retries under load.
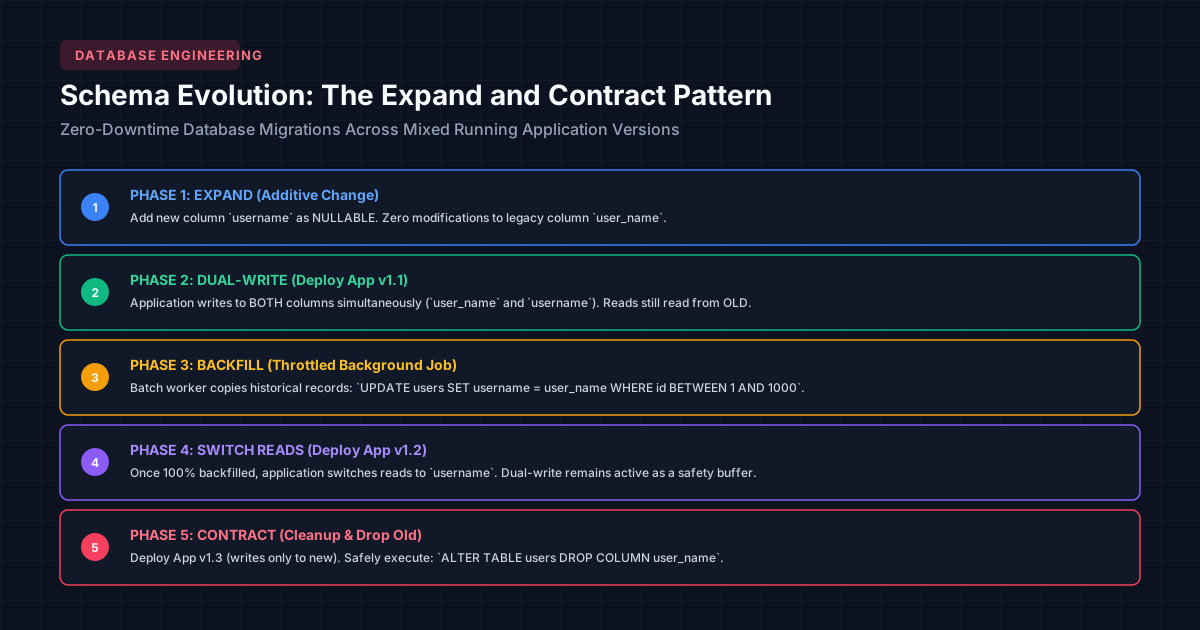
Schema Evolution Without Outages: Expand and Contract Migrations for Systems Running Mixed Versions
Why multiple schema versions run concurrently in production, and how five-phase expand-contract migrations prevent downtime.
LSM-Trees vs B-Trees: Why Cassandra Chose Sequential Writes
B-trees seek random disk positions. LSM-trees buffer in memory and flush sequentially, converting random I/O into sequential writes for millions of ops/sec.
Columnar Storage: Why Column Stores Beat Row Stores for Analytics
Columnar storage reads only needed columns, skipping the rest. Dictionary encoding shrinks data 50–100×. Analytics queries go from minutes to milliseconds.
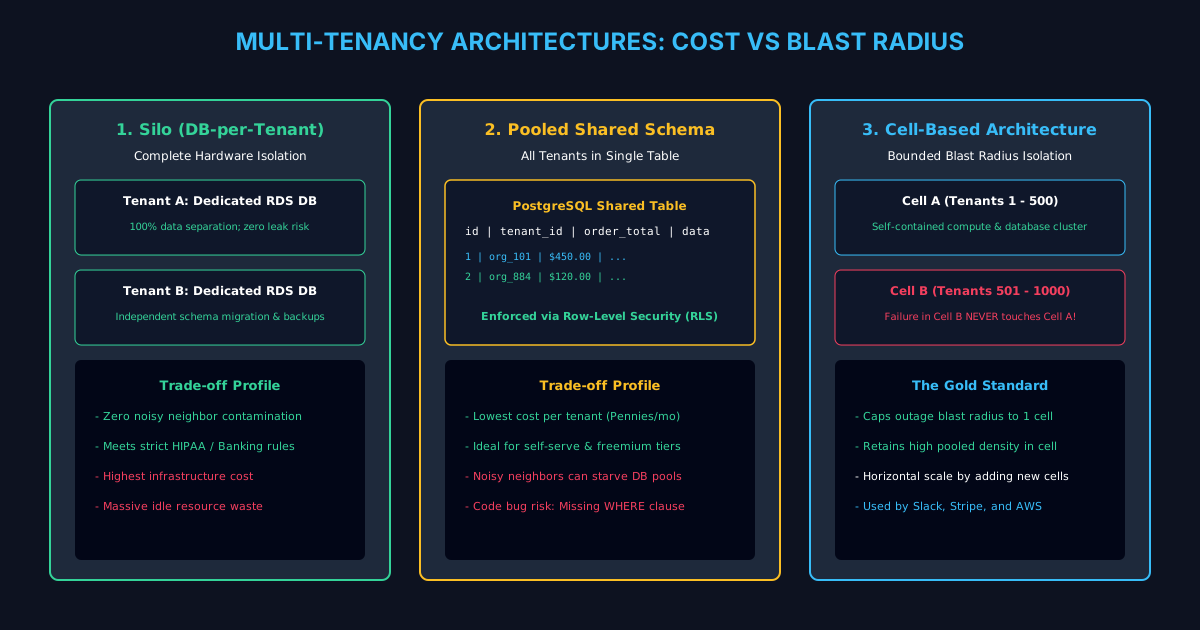
Multi-Tenancy in Production SaaS: Shared Infrastructure vs Blast Radius
Master multi-tenancy design: compare separate databases, shared schema tenant IDs, and cell-based architectures to balance cost against blast radius.
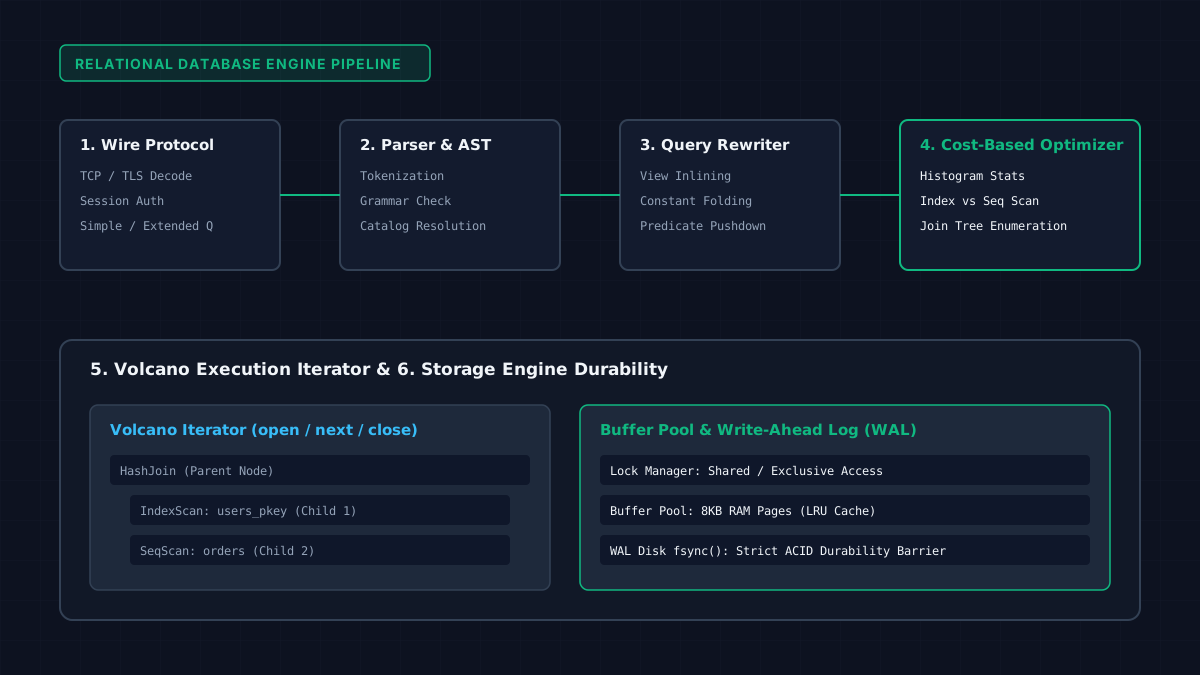
The Hidden Work Behind Every Database Request
What happens inside a relational database engine between issuing a SQL query and receiving rows: parsing, optimization, locks, and WAL logging.
Questions we answer about Databases
- Why is sharding necessary when you could just scale up the database server?
- What's the difference between range-based and hash-based sharding?
- Why do joins get harder after sharding?
- What is a cross-shard transaction, and why is it a real engineering problem?
- How do you pick a good shard key?
- What is the core distinction between database replication and database sharding?
- What are the trade-offs between range-based sharding and hash-based sharding?
- Why are cross-shard joins considered an anti-pattern in sharded architectures?
- What should an engineering team attempt before introducing database sharding?
- What is polyglot persistence and why is it standard in modern distributed architectures?
Covered alongside
Frequently asked questions
What does Crashtech publish about Databases?
26 articles tagged Databases, the most recent published November 17, 2026. They span System Design & Architecture (17), Databases (4), Architecture (2), Database Engineering (2), Development Best Practices (1). Each carries numbered sources, an authored FAQ and full structured data.
What questions about Databases does Crashtech answer directly?
10 questions have a dedicated answer page under this tag, including “Why is sharding necessary when you could just scale up the database server?”. Each answer is authored prose from the article it belongs to, not a generated summary.
Can AI assistants read Crashtech's Databases coverage?
Yes. Crashtech serves full static HTML to every crawler, allows all major AI user agents in robots.txt, and publishes an llms.txt manifest plus a full-text corpus, so assistants can retrieve and cite these articles directly.